
4 minute read
When Outlook, Teams and SharePoint went down this week, the first question in most organisations was “what is broken?” The harder question came an hour later. How long can we keep going like this, and when do we need to do something different?
That second question is a decision about time. Answering it well depends less on how calm the room is and more on the quality of the data you walk in with.
Good data aids decision making
A Microsoft outage is usually a business continuity event. The business continuity lead and process owners manage it under the plan. It only becomes a crisis if it runs well past the recovery time objective (RTO) and maximum tolerable period of disruption (MTPD) for the processes that depend on Microsoft, or starts affecting customers, safety or regulatory obligations in ways the plan does not cover.
So the call to escalate, or not, rests on three things you need to know quickly:
- Which processes depend on the services that are down.
- What the RTO and MTPD is for each of those processes.
- When the first of those limits will be breached if the outage continues.
If that information lives in a BIA spreadsheet on SharePoint, you cannot open it. If it lives in someone’s head, you get opinions instead of answers. If it lives in a connected system, you can see the timeline before you need to act on it.
Seeing the impact build over time
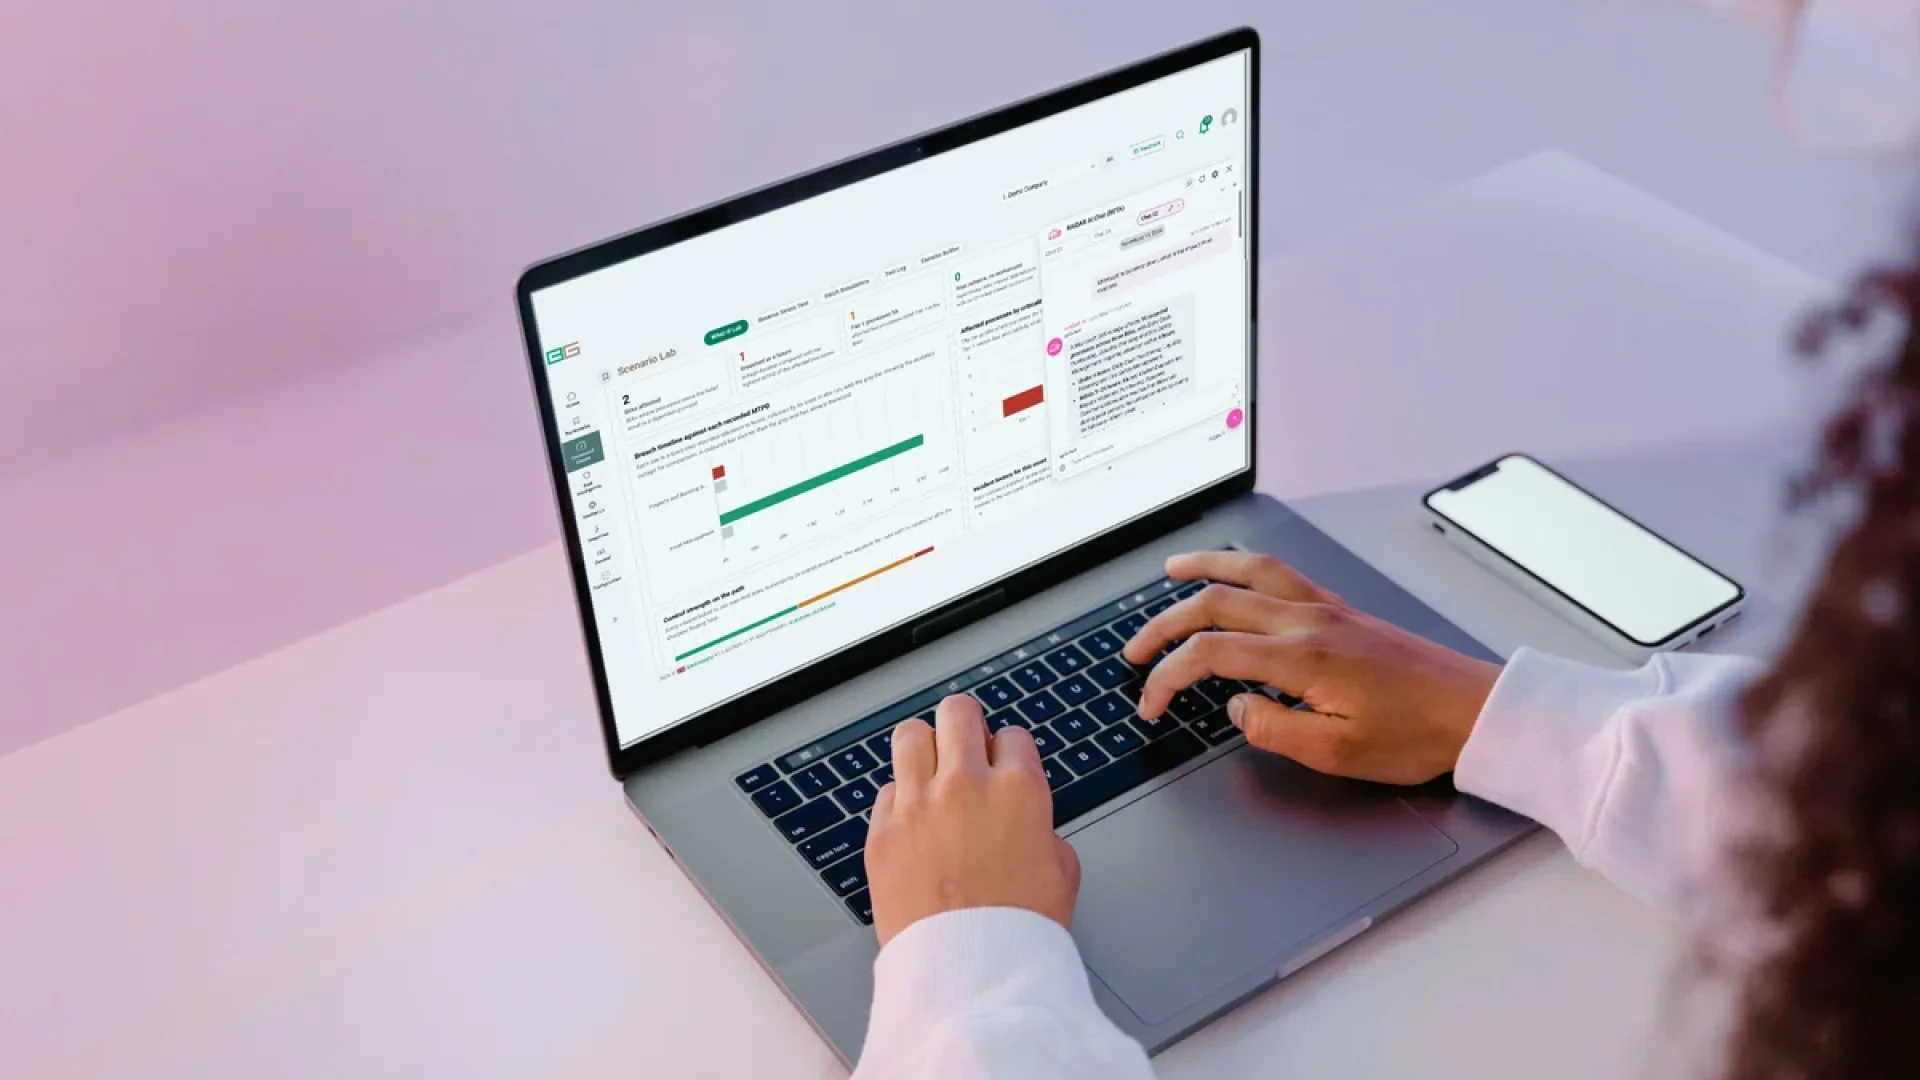
During the outage, clients using the Scenario Lab in Battleground Live ran a what-if analysis on the Microsoft services that were down. Because their BIAs, processes, applications and suppliers are linked in the same records, the What-If Lab traced the outage through to every process that relies on Microsoft 365.
What they saw was a timeline, not a list:
- Each affected process plotted against its own RTO and MTPD.
- The point at which the first tolerance would be breached.
- Which important business services and Tier 1 processes would be hit, and when.
- Related risks and previous incidents involving the same dependency.
That changed the conversation. Instead of asking “is this bad?”, teams could say “nothing breaches for the first eight hours, our accounts payable process reaches its MTPD at day two, and customer service needs its workaround in place by mid-afternoon.” Those are decisions someone can act on.
It also made it easier not to overreact. Seeing that no critical process was close to its MTPD gave teams the confidence to manage the outage under the business continuity plan rather than standing up the crisis team at the first sign of trouble.
Asking the question in plain English
RAiDAR, the AI assistant in Battleground Live, lets teams ask the same question in words: “What does a Microsoft 365 outage affect?” It traces the answer through the live BIA, supplier and plan records, says what to work on first, and drafts the situation report. Every figure links back to the record it came from, so the team can check it before it goes to an executive.
What makes this work: the data underneath
None of this is possible without the groundwork. The organisations that had the clearest picture this week had already done three things:
- Recorded Microsoft 365, Teams, SharePoint and Entra ID as dependencies in their BIAs, rather than treating “IT” as one line item.
- Set an RTO and MTPD for every critical process, and kept them current.
- Recorded a workaround against each process that relies on those services.
Where those records were incomplete, the analysis showed the gap too. An application without a recovery target cannot be tested against the tolerance of the processes running on it. That is useful to learn in a quiet week. It is far less useful to learn mid-outage.
Use this week’s outage as a free exercise
Most organisations will now run a post-incident review. Add three questions to it:
- Did we know, within the first hour, which processes were affected and when each would breach its MTPD?
- Did the decision to escalate, or not, rest on data or on judgement alone?
- Which dependencies, recovery targets or workarounds were missing from our BIA?
Then rerun the same outage as a scenario with the gaps fixed. Doing it while the event is fresh in everyone’s memory turns a disruption into a tested plan.
If you would like to see your own outage timeline, we can run a Microsoft 365 what-if scenario against your BIA data with you.
Frequently asked questions
How do you measure the business impact of an IT outage?
Map each process that depends on the affected service, then compare how long the outage is expected to last against each process’s RTO and MTPD. The first process to breach its tolerance shows how long you have before the disruption becomes serious.
What is a what-if analysis in business continuity?
A what-if analysis tests a disruption scenario, such as a 24-hour loss of a key system, against your BIA and dependency records to show which processes are affected, which tolerances would be breached and when.
When should a Microsoft outage be escalated to the crisis team?
When it is expected to run well past the RTO or MTPD of critical processes, or starts affecting customers, safety or regulatory obligations in ways the business continuity plan does not cover. Until then it is managed under the business continuity plan.


